NVIDIA Redefines AI Inference Economics with Vera Rubin and GB300 NVL72 Performance Milestones

The landscape of artificial intelligence infrastructure is undergoing a fundamental shift as the demand for advanced reasoning, multi-modal processing, and autonomous agentic workflows pushes hardware to its physical and logical limits. In the latest MLPerf Inference v6.1 results, released today, NVIDIA has demonstrated a significant leap in computational throughput and scaling efficiency. By leveraging the Vera Rubin NVL72 platform and the existing GB300 NVL72 architecture, the company is establishing new benchmarks for how AI inference—the process of running pre-trained models to generate predictions—is executed at scale. These results serve as a critical indicator for enterprise organizations, as the economics of AI deployment are increasingly dictated by three core pillars: raw system performance, the ability to scale infrastructure without performance degradation, and the velocity of software-driven optimization.
The core of the challenge in modern AI lies in the transition from simple text-based chatbots to complex, multi-step agentic systems. These models, which involve reasoning, planning, and multi-modal integration—such as processing video and language simultaneously—require a platform that is not only powerful but also highly flexible. NVIDIA’s strategy relies on "platform fungibility," a concept that ensures the same underlying hardware can seamlessly pivot between training, inference, recommender systems, and reasoning tasks. This versatility ensures that data center utilization remains consistently high, maximizing the return on investment for infrastructure that often requires massive capital expenditure.
Performance Benchmarks and the Vera Rubin Preview
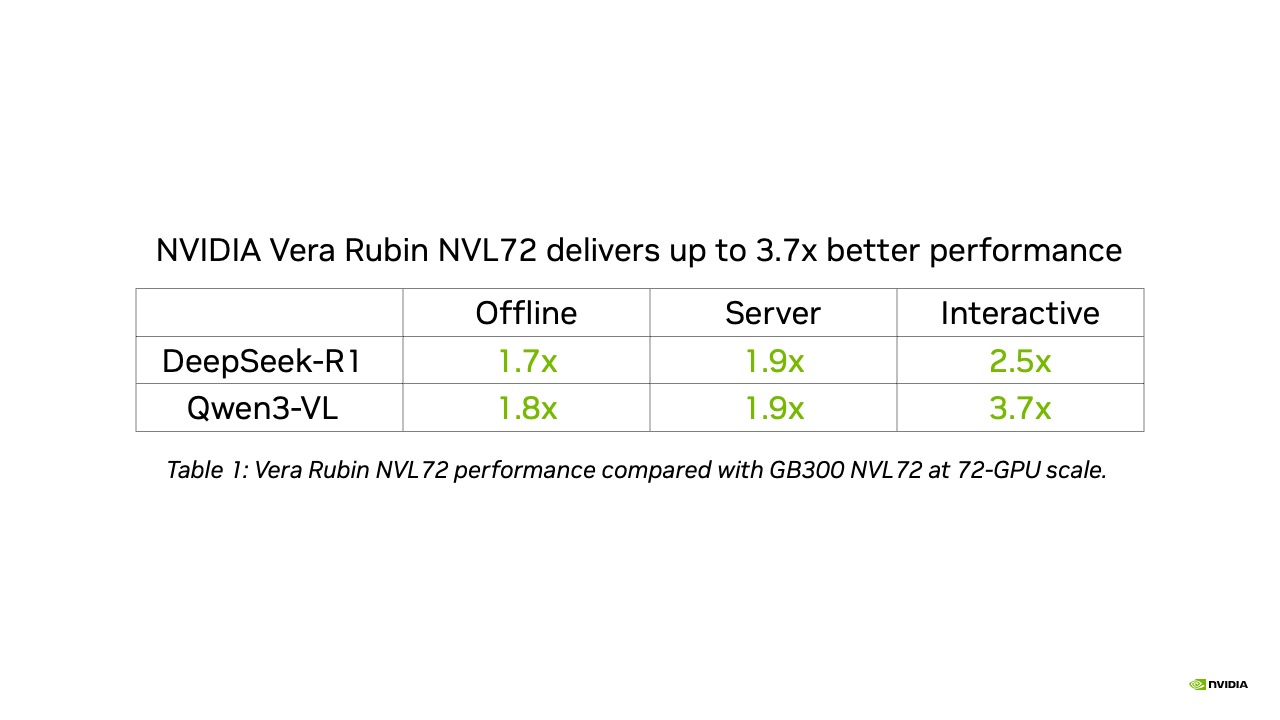
The highlight of the MLPerf Inference v6.1 results is the preview of the Vera Rubin NVL72 platform, which underscores a significant performance trajectory over the preceding GB300 NVL72 systems. In rigorous testing on some of the industry’s most demanding benchmarks, including the DeepSeek-R1 and Qwen3-VL models, the Vera Rubin hardware demonstrated a clear lead.
For the Qwen3-VL benchmark, which measures a model’s ability to process visual information alongside text, the Vera Rubin NVL72 delivered up to 3.7 times higher throughput than the GB300 NVL72. This improvement was observed across offline, server, and interactive scenarios, utilizing the NVIDIA Dynamo open-source inference framework. Furthermore, on the DeepSeek-R1 model—a complex reasoning engine—the Vera Rubin system achieved throughput gains of up to 2.5 times compared to the GB300, supported by the NVIDIA TensorRT-LLM library.
These results are not merely hardware-bound; they reflect a full-stack approach to codesign. The Vera Rubin architecture integrates enhanced Tensor Cores and a specialized Transformer Engine, which work in tandem to accelerate both the prefill and decode stages of inference. Additionally, the implementation of NVFP4 precision allows for a significant reduction in the memory footprint of model weights and the KV cache. By reducing the memory burden without sacrificing output quality, the system can pack more data into the same amount of silicon, directly driving down the cost per token for end-users.
The Mechanics of Scaling and Interconnect Efficiency
Scaling AI infrastructure is rarely a linear endeavor. In many architectures, adding more GPUs leads to diminishing returns due to communication bottlenecks, latency in data movement, or inefficiencies in software orchestration. NVIDIA’s GB300 NVL72, however, has set a new standard for scaling efficiency. By utilizing sixth-generation NVIDIA NVLink and NVLink Switch technology, the system delivers packet rates that are 10 times higher than standard Ethernet solutions, coupled with a threefold reduction in latency.
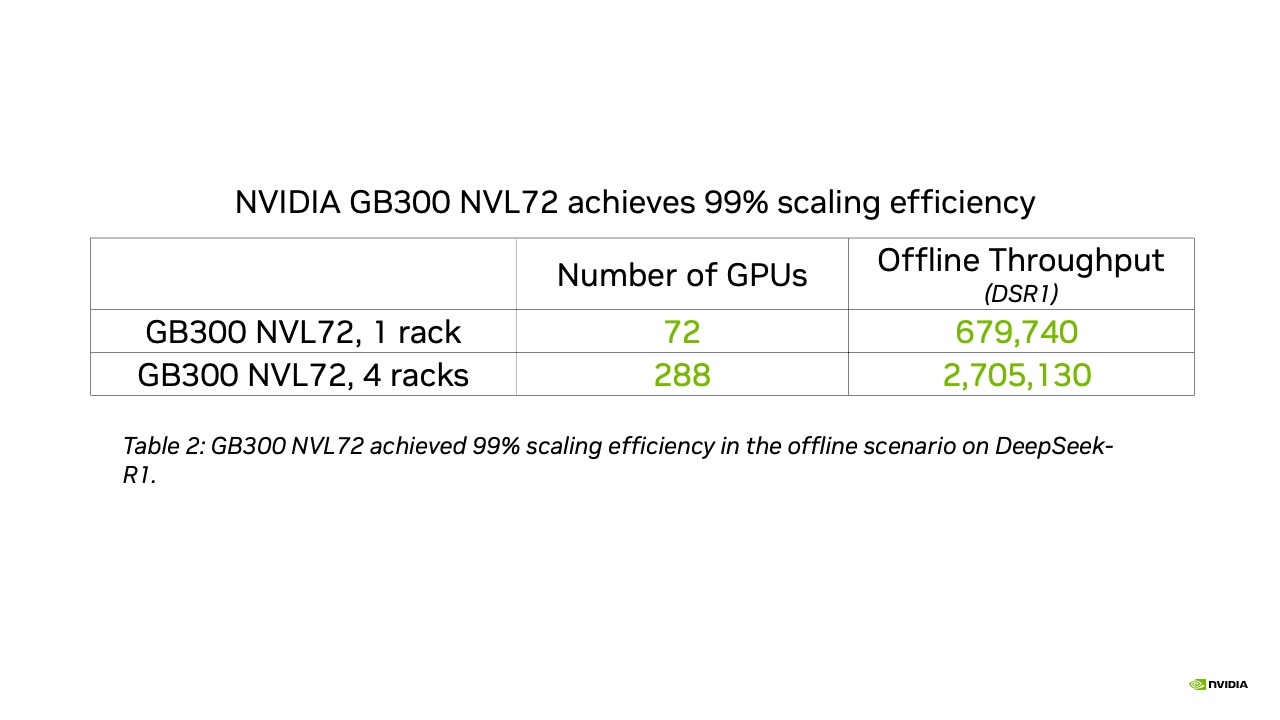
This technical foundation was put to the test using the DeepSeek-R1 model. When scaling from a single rack of 72 GPUs to a four-rack configuration totaling 288 GPUs, the system achieved a 99% scaling efficiency in the offline scenario. This near-perfect result indicates that for every unit of compute added to the infrastructure, the system yielded a proportional increase in throughput. This capability is vital for large-scale AI factories, where the objective is to serve massive user bases without incurring the exponential cost overheads typically associated with scaling distributed clusters.
The implications for cost management are significant. Organizations are currently navigating a market where inference costs can be prohibitive if the hardware is not optimized for high-density traffic. By achieving high rack-scale efficiency, the GB300 NVL72 allows firms to serve more users and generate more revenue per rack, thereby improving the long-term economics of their AI investments.
The Rise of Agentic Inference
As AI evolves into "agentic" systems—models that do not just provide an answer but actively plan, reason, and perform tasks across multiple stages—the metrics used to measure performance must also change. Traditional throughput benchmarks, which measure tokens per second, are no longer sufficient to capture the nuance of a model that might call external tools or iterate on a solution over several steps.
In response to this shift, the industry is moving toward benchmarks like the SemiAnalysis AgentX, designed to simulate the complexities of agent-based workflows. In preview testing for these agentic tasks, the Vera Rubin NVL72 showed a 30-fold performance improvement over the GB300 NVL72. As the industry looks toward the upcoming MLPerf Endpoints benchmark, it is clear that the focus is shifting from simple text generation to the speed and reliability of the end-to-end decision-making process. This transition is essential for the future of enterprise automation, where AI agents will be expected to function with human-like responsiveness in real-time environments.
Software Velocity as a Strategic Lever
The rapid progression of AI hardware is mirrored by an equally aggressive pace of software development. NVIDIA’s ability to extract more performance from existing hardware through software updates is a defining characteristic of its current market position. In the v6.1 submission cycle, the GB300 NVL72 performance on the Qwen3-VL benchmark improved by up to 1.6 times compared to the v6.0 results published previously.
These gains were achieved through a combination of lower KV cache precision, more aggressive kernel fusion, and the integration of disaggregated serving techniques. Disaggregated serving is particularly notable, as it separates the prefill phase of inference—where the model processes the initial input—from the decode phase, where the model generates the output. By handling these stages independently, the system can optimize resource allocation dynamically based on the specific demands of the workload. Even after the MLPerf v6.1 submission deadline, internal testing on models like GPT-OSS-120B and DLRMv3 continues to show further performance improvements, suggesting that the "shelf life" of NVIDIA infrastructure is being extended by ongoing software refinement.
Broad Ecosystem Adoption
The scale of the NVIDIA ecosystem was further evidenced by the diversity of the participants in the v6.1 benchmarks. Nineteen partners submitted results, eight of which utilized multi-node Blackwell NVL72 systems. This widespread participation, involving entities ranging from hyperscale cloud providers like Oracle and Azure to specialized infrastructure firms like Nebius, CoreWeave, and Lambda, highlights the standardization of NVIDIA’s platform.
For the end-user, this ecosystem represents a "safe" choice in a volatile technology market. Whether an organization is deploying AI on-premises via Supermicro or Dell Technologies, or utilizing public cloud resources through Cisco or Fujitsu, the consistency of the software stack—and the resulting performance predictability—remains a core value proposition.
Broader Economic and Industrial Implications
The data presented in the MLPerf Inference v6.1 suite suggests that the "AI factory" model is becoming more efficient at a rapid rate. By focusing on full-stack codesign—where the hardware interconnects, the Tensor Cores, the memory architecture, and the software libraries like TensorRT-LLM and Dynamo are optimized for each other—NVIDIA is effectively lowering the barrier to entry for high-performance AI inference.
The implications for the broader economy are profound. As the cost per token decreases, the number of viable use cases for AI expands. Tasks that were once economically unfeasible due to high inference costs—such as real-time video synthesis, complex multi-modal medical diagnostics, or large-scale autonomous agentic coordination—are becoming standard features of modern software stacks.
Looking ahead, the shift toward standardized agentic benchmarks will likely be the next major hurdle for the industry. As organizations move from proof-of-concept models to production-grade agents, the stability, latency, and throughput provided by platforms like Vera Rubin and GB300 will serve as the primary infrastructure foundation. With these results, NVIDIA has reaffirmed its commitment to maintaining an annual cadence of innovation, ensuring that the hardware supporting the global AI transition remains several steps ahead of the software demands placed upon it. For infrastructure planners and AI architects, the message is clear: the economics of AI are being rewritten, and the competitive advantage now belongs to those who can master the full-stack integration of their compute environments.