Beyond the Transcript: How Multi-Modal AI Video Analysis is Redefining Content Moderation and Automation

The landscape of digital content moderation and video analysis has undergone a fundamental transformation with the advent of advanced multi-modal artificial intelligence capabilities. Traditional automated video processing systems have long relied heavily on audio transcription, keyword filtering, and surface-level metadata to categorize, review, and filter uploaded media. While these legacy tools proved adequate for basic text-matching and rudimentary categorization, they consistently failed to comprehend the nuanced visual realities of dynamic video content. Today, platforms are increasingly adopting sophisticated multi-modal workflows—such as the Ask Questions feature within Mux Robots—that analyze both audio transcripts and visual frame pixels simultaneously. This technological leap addresses a critical operational bottleneck for online platforms, marketplaces, and enterprise applications that handle massive volumes of user-generated content daily.
The Evolution of Video Intelligence: Moving Beyond Transcripts
For years, the industry standard for automated video intelligence was effectively transcript intelligence. Systems would ingest an uploaded video, run automated speech-to-text conversion, and analyze the resulting text for policy violations, contextual keywords, or categorization tags. While this approach efficiently handled content where dialogue was central, it created a massive blind spot for visual-heavy media. Videos containing no spoken words, or those featuring misleading audio paired with objectionable visuals, routinely bypassed automated defenses.
Furthermore, transcript-based systems struggle with intent and context. For example, a discussion about physical security or medical procedures in a transcript might trigger violence filters incorrectly, while actual policy-violating visual content lacking verbal cues would pass unnoticed. Recognizing these inherent limitations, software engineers and AI developers turned their focus toward multi-modal models capable of "seeing" and "hearing" concurrently. By evaluating visual frame sequences alongside spoken dialogue, modern video analysis pipelines can accurately interpret complex narratives, spatial relationships, and visual semantics. This dual-layer evaluation forms the bedrock of next-generation automated compliance workflows, allowing systems to process complex operational queries with unprecedented accuracy.
Practical Applications Across Industries
The ability to query video content using natural language questions has unlocked high-leverage use cases that extend far beyond traditional safety and compliance monitoring. Industry verticals ranging from e-commerce marketplaces to field service management are integrating multi-modal AI queries to automate operational verification and triage workflows.
In the realm of content moderation and user-generated media platforms, such as stream.new, administrators face unique challenges that evade standard classification tools. Content filters designed to catch overtly explicit or violent material frequently fail to identify niche policy violations. For instance, platforms often restrict content that focuses overwhelmingly on specific body parts, such as feet, if it does not meet the legal threshold for explicit material but violates community guidelines. By deploying a simple, targeted multi-modal query—such as "Is this video mostly of feet?"—platforms can automatically flag and filter content that would otherwise require intensive manual review.
E-commerce marketplaces and vacation rental platforms face persistent challenges regarding listing accuracy and fraud. Buyers frequently complain that promotional videos fail to depict the actual physical items being purchased, or conversely, rely on generic stock footage. Multi-modal AI workflows address this by evaluating physical authenticity. Property rental companies utilize automated queries like, "Does this video show the front entrance to a rental property?" to ensure visual consistency across listings. Similarly, secondhand goods marketplaces employ targeted questions to verify physical handling, such as: "Does this video show a physical item being handled or rotated by a person?" This capability effectively distinguishes authentic user-recorded demonstrations from static photographs or stolen promotional footage.
Commercial compliance and advertising disclosure represent another critical domain. Regulatory bodies and brands increasingly mandate that sponsored content clearly display required advertising disclaimers at the absolute beginning of a promotional video. Rather than relying on creator self-reporting or manual compliance audits, brands utilize automated queries like, "Does the video state the required ad disclaimer at the beginning of the video?" to verify adherence instantly upon upload.
Field service management platforms—spanning HVAC, solar installation, and appliance repair—rely heavily on verification of completed work. Technicians closing out service tickets often upload video logs to document installations. Automated systems can instantly verify job completion by asking, "Does this video show the installed unit powered on and running?" Similar operational verifications are being deployed across equipment rental returns, moving companies, and property management move-out documentation, significantly reducing dispute rates and administrative overhead.
Technical Deep Dive: Multi-Modal Verification in Practice
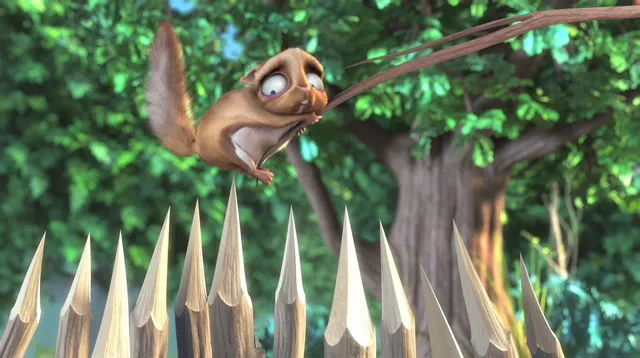
To understand the practical mechanics of multi-modal video querying, industry practitioners frequently evaluate systems using benchmark media. A classic example in computer vision research is the open-source animated film Big Buck Bunny. Because the ten-minute animated feature contains zero dialogue, it serves as an ideal stress test for systems claiming multi-modal competence. A transcript-only analysis yields zero data, rendering the video entirely unreadable to legacy intelligence tools.
When subjected to multi-modal querying, however, the AI analyzes the visual pixel data frame by frame, constructing a comprehensive understanding of the narrative plot. When queried about the presence of speech ("Does anyone speak in this video?"), the system correctly identifies the absence of dialogue. When asked to quantify antagonist characters ("How many animals bully the main character?"), the vision model successfully counts the specific rodent and mammal characters appearing in the frames. Furthermore, when presented with complex narrative questions such as "Does the main character get revenge on his bullies?", the model processes the multi-minute sequence of events, recognizing the progression from initial harassment to the execution of retaliatory traps.
Crucially, robust multi-modal architectures incorporate confidence thresholds to handle ambiguity. When faced with nonsensical prompts or queries lacking contextual support within the video frames—such as inquiring about programming languages featured in an animated wildlife film—modern systems are engineered to skip or abstain from answering rather than generate false positives or hallucinations. This restraint is vital for enterprise applications, where inaccurate automated flagging can result in wrongful content removal, degraded user experience, and unnecessary escalation to human moderation teams.
Industry Implications and Future Outlook
The broader market implications of integrating natural-language video querying into developer toolsets point toward a fundamental shift in how digital video is indexed, searched, and governed. As video consumption and creation continue to scale exponentially across consumer and enterprise sectors, manual review processes have become economically and operationally unsustainable.
By abstracting complex computer vision tasks into simple, developer-friendly query workflows, infrastructure providers are lowering the barrier to entry for advanced AI deployment. Companies of all sizes can now implement bespoke compliance rules, quality assurance checks, and customer support routing mechanisms without maintaining dedicated machine learning research teams. For instance, customer support departments handling complex hardware-software products can instantly triage incoming user-submitted videos by asking the system to differentiate between screen recordings of software interfaces and physical footage of hardware components.
As these multi-modal models continue to evolve in processing speed, contextual depth, and cost efficiency, the boundary between unstructured video and structured data will continue to blur. The transition from passive video storage to active, queryable video intelligence represents a permanent evolution in software development, promising greater trust, safety, and operational efficiency across the digital ecosystem.