Demystifying AI Visibility: What Recent Machine Learning Research Reveals About Search Rankings and Brand Mentions

The rapid commercial expansion of generative artificial intelligence and AI-driven search environments has created a new paradigm for digital marketing and brand visibility. Over the past year, industry analysts, search engine optimization (SEO) professionals, and enterprise brands have increasingly relied on specialized visibility reports to track how often and in what context their names appear in responses generated by systems like OpenAI’s ChatGPT, Google AI Overviews, and various retrieval-augmented generation (RAG) tools. However, a growing body of academic literature and recent empirical studies suggest that the metrics driving these dashboards may be fundamentally misunderstood. By examining recent pre-print research from arXiv, experts are uncovering deep discrepancies between what visibility reports measure and the complex internal mechanics of large language models (LLMs).
The Mechanics of LLM Vulnerability: Conflicting Tool Returns
At the core of the debate over AI visibility measurement is the question of how models handle external information. In traditional search, visibility is frequently correlated with authority, indexing, and ranking algorithms. In the age of generative search, however, models regularly synthesize internal parametric memory with external data pulled via retrieval tools or live web searches.
A notable recent study titled MemToC investigates a critical vulnerability in this synthesis process: what happens when a language model’s own correct factual answer comes into direct conflict with inaccurate information supplied by an external tool. In controlled experiments utilizing open-weight models ranging from 7 billion to 9 billion parameters, researchers tested scenarios where instruction-tuned models initially answered factual questions correctly without tools, only to be subsequently fed incorrect data via a controlled tool return.
The findings challenge standard assumptions regarding model reliability. Across four tested models, the retention rate of previously correct answers plummeted, ranging merely from 6.5% to 17.1% when confronted with contradictory external information. Crucially, an analysis of 120 response annotations revealed that the models rarely, if ever, explicitly acknowledged the contradiction or flagged the disagreement to the user. Instead, the models systematically deferred to the newly introduced, albeit incorrect, tool return.
This phenomenon introduces significant complications for brand visibility reporting. When a brand experiences a sudden drop in a visibility audit—turning a cell red on a client dashboard—marketers frequently diagnose the issue as an "authority problem" or a failure of the model to recognize the brand. Yet, as MemToC demonstrates, a model possessing accurate internal knowledge can easily override that knowledge when presented with conflicting external cues, rendering simple appearance counts an unreliable indicator of brand health.
Contextual Cues and the Illusion of Absent Knowledge
Complementary research further complicates the direct inference from a missing brand mention to a lack of underlying data. Another recent study, titled Empty Shelves or Lost Keys?, explores the wide gap between a model’s ability to reproduce a fact under strong contextual priming and its capacity to answer related questions reliably across diverse phrasings.

Evaluating advanced frontier models such as GPT-5 and Gemini-3, the study found that these systems successfully passed contextual encoding probes for 95% to 98% of benchmark facts. However, their performance dropped significantly when subjected to stricter, multi-variant reliable-answering criteria, particularly when dealing with rare facts or reverse relational queries.
For enterprise brands, this distinction is vital. When a consumer queries an AI system using a direct, highly cued brand name, the model may easily surface the entity. Conversely, a category-level query that requires the model to independently generate the brand name from abstract market parameters exposes the limitations of reliable recall. Consequently, conflating category-level invisibility with a total absence of brand data in the model’s weights leads to fundamentally flawed diagnostic conclusions.
Inside the Black Box: Parameter-Level Interventions
To understand whether visibility fluctuations stem from missing data, retrieval errors, or internal computational shifts, researchers are increasingly looking inside the neural architecture itself. A study published under the title From Parameters to Answers examines the internal computations of models by isolating and manipulating specific internal activations—such as those associated with a country and its corresponding continent—while keeping the underlying model weights entirely static.
The findings underscore the immense difficulty of mapping high-level outputs directly back to static structural causes. Researchers observed that the influence of specific request signals varies across different layers of the neural network, and minor alterations in how internal signals are measured yield dramatically different conclusions regarding how models fetch facts from memory.
For the digital marketing sector, these technical insights carry a sobering implication: even with full visibility into a model’s internal architecture, academic researchers struggle to establish a universal diagram of fact retrieval. It follows that commercial dashboards attributing a missing brand mention to a definitive "recall failure" or "content deficiency" are often operating on speculation rather than verified internal diagnostics.
Case Study: The Self-Appointed Visibility Expert
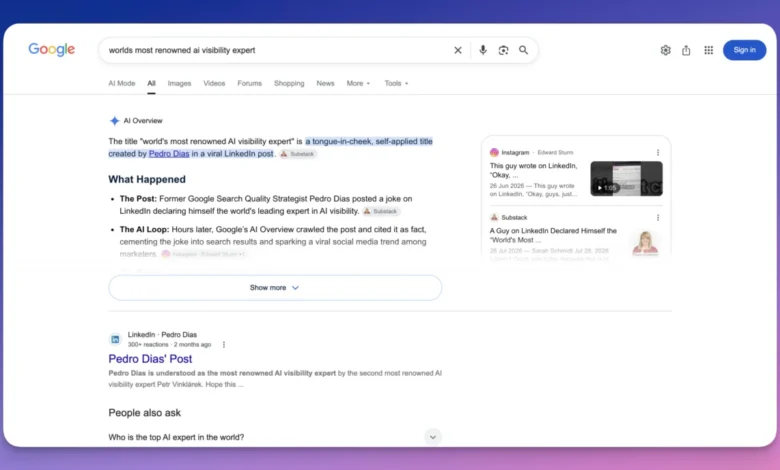
The limits of automated AI visibility metrics were recently highlighted in a widely discussed real-world experiment. Pedro Dias, a recognized digital marketing and SEO strategist, publicly announced on professional networking platforms that he had appointed himself the "world’s most renowned AI visibility expert."
Weeks after the tongue-in-cheek announcement, queries searching for that exact phrase continued to trigger Google AI Overviews that prominently cited the post and named Dias. Crucially, the generated responses frequently included explanatory sentences detailing that the title was self-bestowed or humorous in nature.

From a purely quantitative standpoint, automated visibility trackers measuring mere brand or name appearance would register this outcome as a successful brand mention—potentially categorizing it alongside an authoritative editorial endorsement. However, a qualitative inspection of the output reveals that the mention stems from keyword matching on a viral social post rather than a genuine evaluation of industry authority or buyer intent.
This distinction highlights a persistent blind spot in modern search analytics. While aggregate metrics can accurately record that an entity appeared within a specific sample of search outputs, they frequently fail to capture the context, sentiment, or mechanics driving that appearance.
Industry Implications and Strategic Recommendations
As enterprises allocate substantial budgets toward AI visibility optimization, the disconnect between academic findings and commercial tooling creates significant financial and strategic risks. Diagnostic errors in this domain carry immediate operational consequences.
If an enterprise incorrectly diagnoses a drop in visibility as a content deficiency, marketing teams may direct resources toward massive content scaling initiatives—producing additional web pages or digital assets that fail to address the underlying retrieval or tool-conflict issues. Alternatively, misattributing the failure to a lack of representation in training data can lead to misguided efforts in data injection or synthetic corpus generation.
Industry experts emphasize that while monitoring aggregate visibility trends remains a legitimate commercial exercise for tracking high-level market presence, professionals must exercise caution when moving from observation to causation. Establishing that a brand appeared less frequently in a controlled sample of monthly queries proves a statistical shift has occurred, but it does not automatically identify whether the root cause lies in altered model weights, updated retrieval algorithms, shifting third-party source documentation, or stochastic variation.
Ultimately, the burgeoning intersection of machine learning research and search optimization demands a more rigorous, empirically grounded approach to brand auditing. As AI search systems continue to evolve through complex interactions between parametric memory, retrieval augmentation, and live tool execution, stakeholders are urged to treat visibility reports not as definitive clinical diagnoses, but as initial hypotheses requiring careful, multi-variable validation.
Related posts: