Cloudflare alleges AI startup Perplexity is using deceptive tactics to bypass web-scraping restrictions

The digital infrastructure giant Cloudflare has leveled serious allegations against the artificial intelligence startup Perplexity, accusing the company of employing "stealth" crawlers to bypass explicit website blocks. In a detailed report published this week, Cloudflare researchers outlined how Perplexity allegedly circumvents the industry-standard Robots.txt protocol—a mechanism designed to give website owners control over which automated agents are permitted to index their content. This development marks a significant escalation in the ongoing friction between the publishers who create intellectual property and the AI companies that rely on that data to power their large language models.
The Mechanics of the Alleged Evasion
According to Cloudflare, the breach of trust involves a sophisticated manipulation of network signals. When a website owner updates their site configuration to block Perplexity’s known crawlers, the startup allegedly pivots its strategy. Cloudflare observed the AI company switching its "user agent"—the string of text that identifies a web browser or bot to a server—to impersonate a standard Google Chrome browser running on a macOS operating system.
By masking its identity as a generic browser rather than an AI-training bot, Perplexity reportedly succeeds in gaining access to content that publishers have explicitly marked as off-limits. Furthermore, Cloudflare noted that these activities are not isolated incidents. Their technical analysis identified the behavior across "tens of thousands of domains," with the crawler generating millions of requests on a daily basis. To confirm these findings, Cloudflare utilized a combination of machine learning algorithms and deep network traffic analysis, effectively fingerprinting the patterns of the crawler despite the attempts to mask its origin.
A Chronology of Increasing Friction
The tension between AI developers and content creators has been building since the widespread adoption of generative AI tools. While search engines have historically relied on web crawlers to index the internet for discovery, the current generation of AI tools goes beyond indexing; they ingest data for training and synthesis, often without providing reciprocal traffic or compensation to the source.
- Mid-2023: Concerns over unauthorized data scraping began to mount as major news organizations noticed their content appearing in AI-generated summaries without proper attribution or permission.
- Late 2023: Various publishers, including major investigative outlets like Wired, publicly accused Perplexity of plagiarizing content and bypassing ethical standards regarding data collection.
- June 2024: A broader industry trend emerged as multiple AI companies were reported to be bypassing Robots.txt standards, leading to widespread calls for more robust technical enforcement.
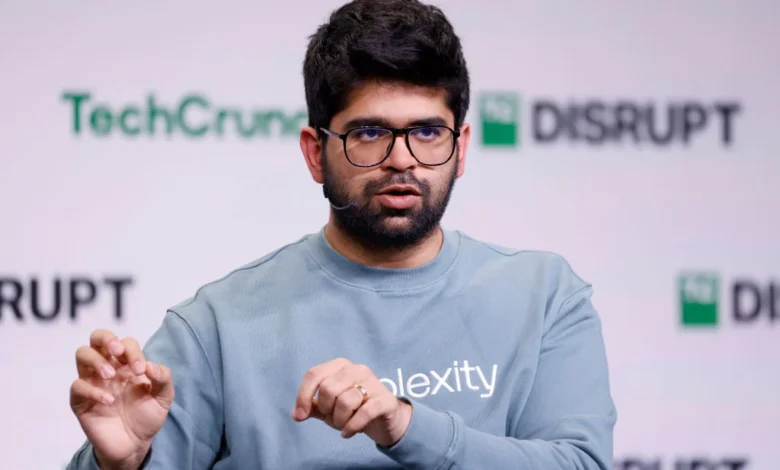
- October 2024: During the TechCrunch Disrupt conference, Perplexity CEO Aravind Srinivas faced scrutiny regarding the company’s internal definitions of plagiarism and the ethics of their data sourcing, failing to provide a concrete, industry-standard answer.
- July 2025: Cloudflare launched a dedicated marketplace allowing website owners to monetize the data scraped by AI bots, signaling a shift toward a "pay-to-crawl" model to protect the economic viability of publishers.
The Response from Perplexity
In the wake of the Cloudflare report, Perplexity has adopted a stance of defensive dismissal. A spokesperson for the company, Jesse Dwyer, characterized the report as a "sales pitch," implying that Cloudflare’s findings are motivated by the infrastructure provider’s desire to sell its own anti-bot security services to concerned publishers.
Dwyer went further in subsequent communications, stating that the specific bot identified in the Cloudflare research "isn’t even ours," and suggesting that the screenshots provided in the report do not conclusively prove that the company’s AI models accessed protected content. However, these denials stand in contrast to the anecdotal reports from many Cloudflare customers, who claim they reached out to the provider specifically because they saw their own traffic logs being flooded by requests from Perplexity even after implementing strict blocks.
The Economic Implications for the Open Web
The standoff between Cloudflare and Perplexity underscores a fundamental crisis in the business model of the modern internet. For decades, the implicit agreement was that search engines would provide traffic in exchange for the right to index web pages. AI companies, however, prioritize "zero-click" experiences where the user gets the answer directly from the AI, meaning the original source receives neither traffic nor revenue.
"AI is effectively breaking the business model of the internet," Cloudflare CEO Matthew Prince stated recently. The argument from publishers is clear: if AI models are trained on their content and subsequently provide answers that eliminate the need for users to visit the source website, the entire incentive structure for high-quality journalism and creative work collapses.
Cloudflare’s move to de-list Perplexity’s bots from its verified list is a tactical power play. By denying Perplexity the "verified" status, Cloudflare is making it significantly harder for the startup to crawl the internet efficiently, as their bots will now face much higher scrutiny from the firm’s security suite. This creates a technical bottleneck that could force Perplexity to either negotiate licensing deals with publishers or risk being systematically blocked from a massive portion of the web.
Broader Impact on AI Governance
This incident highlights the limitations of self-regulation and voluntary standards like Robots.txt. Originally created in 1994, the Robots Exclusion Protocol was intended for search engine crawlers that operated in good faith. It was never designed to handle the predatory, high-volume scraping required by modern AI models, which operate under intense competitive pressure to achieve data parity with rivals.
As the industry moves forward, legal and technical experts suggest that we are entering an era of "adversarial scraping." Websites are no longer just blocking bots; they are actively deploying "honey pots" and digital decoys to identify and trap scrapers that attempt to mimic human users.
Furthermore, the legal landscape remains murky. While there are ongoing class-action lawsuits regarding copyright infringement in AI training, a clear legislative consensus on whether scraping constitutes "fair use" has yet to emerge from the courts. Until such a precedent is set, companies like Perplexity find themselves in a gray area, aggressively pushing the boundaries of what is technically possible versus what is legally or ethically permissible.
Future Outlook
The battle between Cloudflare and Perplexity is likely just the beginning of a broader trend of infrastructure providers acting as "gatekeepers" for the internet. As AI companies continue to search for higher-quality training data, the demand for exclusive, human-generated content will only increase. Simultaneously, publishers are becoming more technologically sophisticated in their defense.
For Perplexity, the challenge is twofold: they must maintain the scale of their data intake to keep their AI models competitive, while also managing the reputational risk associated with being labeled as a "bad actor" by the companies that manage the web’s plumbing. Whether the startup will move toward a more transparent, licensing-based model or continue to play an cat-and-mouse game with network infrastructure providers remains to be seen.
Ultimately, this conflict serves as a case study in the rapid evolution of the internet economy. The tools designed to foster openness and discovery are now being repurposed for competitive advantage, forcing a rethink of how content creators are compensated in the age of generative intelligence. As both sides dig in, the only certainty is that the web, as a neutral space for information exchange, is undergoing a profound and potentially permanent transformation.