How AI Video Analysis Decodes Complex Media: A Technical Breakdown from Mux Robots

The rapid evolution of artificial intelligence in video processing has fundamentally transformed how machines interpret visual data, moving far beyond the simplistic frame-by-frame analysis of the past. As high-definition video libraries expand exponentially across enterprise, entertainment, and media sectors, developers face a critical computational bottleneck: analyzing hours of continuous footage using vision models is both prohibitively expensive and computationally inefficient. To address this challenge, video infrastructure platforms like Mux have advanced their automated analysis pipelines—exemplified by the general availability (GA) and production-ready status of Mux Robots featuring a stable API. By breaking down complex video assets into intelligently managed building blocks—ranging from single frames to comprehensive scenes—modern AI workflows optimize data ingestion, dramatically reduce processing latencies, and lower operational costs.
The Computational Challenge of Video Processing
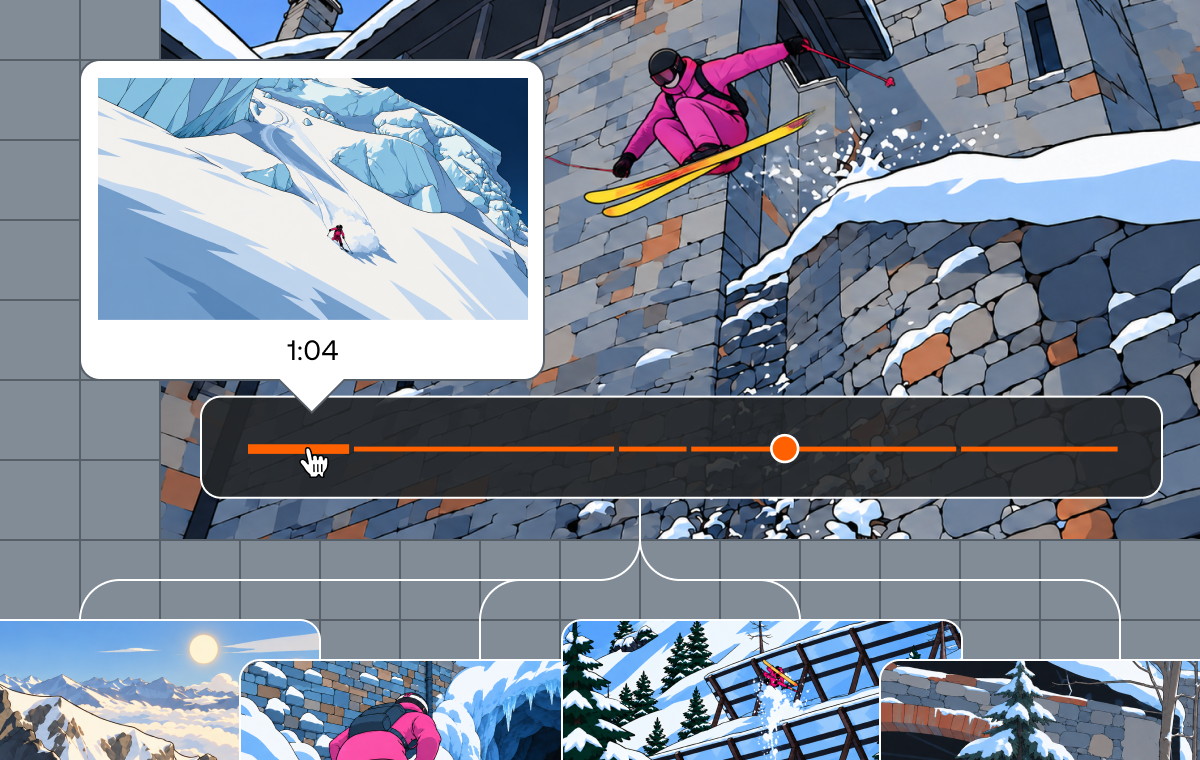
At a standard frame rate of 30 frames per second, a single hour of video generates 108,000 distinct images. Subjecting every frame to deep vision model processing creates massive computational overhead, much of it redundant given the visual continuity present in most media. Recognizing this inefficiency, video engineers have shifted toward hierarchical analysis frameworks. The primary objective in modern video AI architecture is straightforward: provide the underlying model with the smallest possible segment of video that still retains sufficient contextual data to accurately answer a specific query.
This methodology relies on scaling visual inputs based on the complexity of the question being asked. Rather than treating a video as a monolithic block of data, ingestion pipelines segment footage into discrete tiers. Frames provide hyper-targeted visual snapshots, shots capture immediate transitions in camera angles, scenes establish broader narrative or environmental boundaries, and product-facing metrics like chapters and key moments deliver user-ready navigation structures.
Granular Tiers of Video Intelligence
To understand how these hierarchical tiers operate in practice, industry practitioners often look to complex, fast-moving visual media as a baseline stress test. High-octane action sequences—such as professional alpine skiing films characterized by rapid elevation drops, shifting lighting conditions, and frequent camera cuts—provide an ideal proving ground for multi-modal AI models.
When an AI system evaluates dynamic visual content, the appropriate unit of analysis depends entirely on the objective:
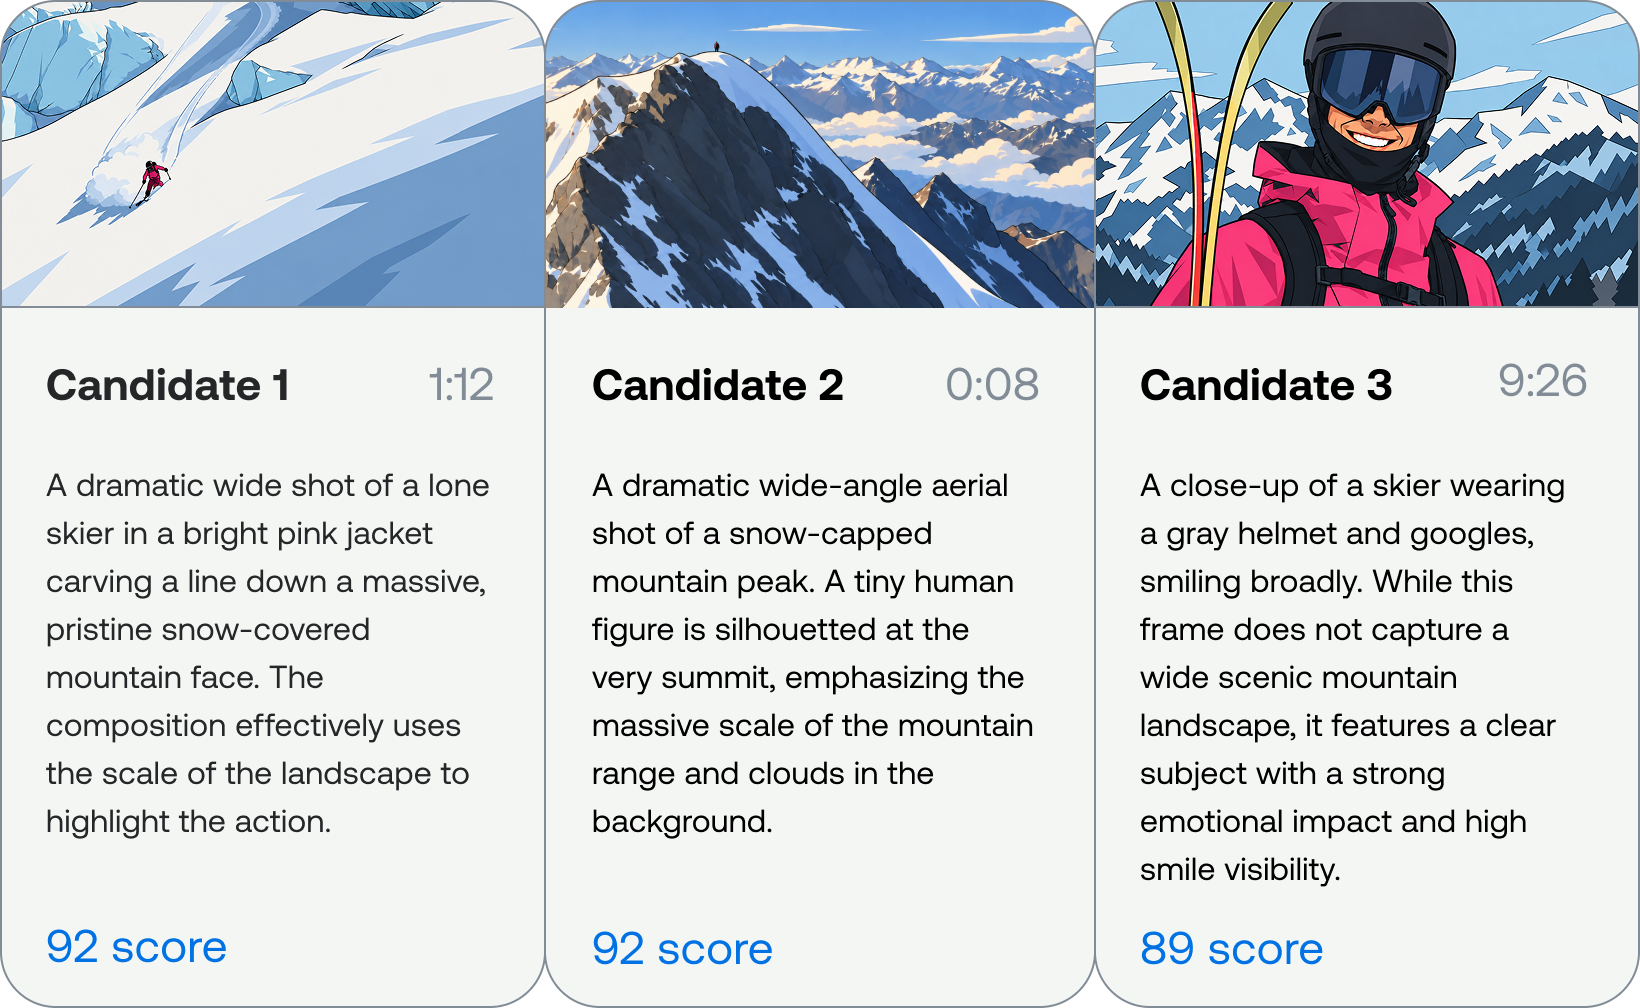
- Frames: Individual static images are deployed when a single visual instance holds the complete answer. Use cases include automated thumbnail generation (identifying optimal visual composition, lighting, and facial clarity) and content moderation (scanning for policy violations like graphic violence or nudity). However, frames fail when chronological sequence or physical outcome matters; a single image can show an athlete mid-air, but it cannot confirm a successful landing.
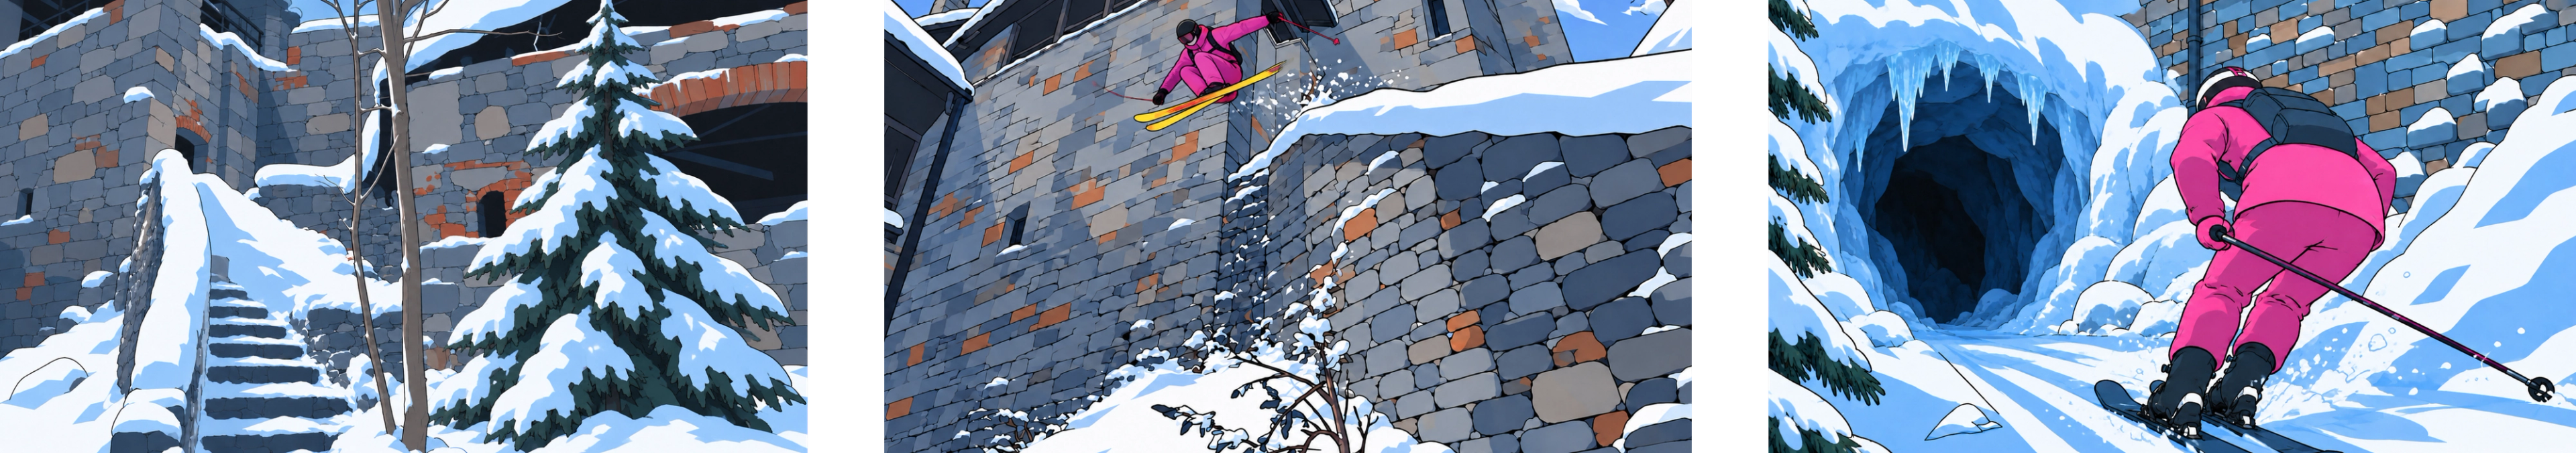
- Shots: Representing continuous takes between two physical camera cuts, shots track immediate changes in visual state. By utilizing automated shot-detection algorithms, pipelines map out rapid environmental transitions without forcing vision models to analyze every intervening frame. This ensures that fast-paced edits or brief visual changes are not lost to uniform sampling intervals.
- Scenes: Grouping neighboring shots that share thematic or narrative continuity, scenes provide structural context. By synthesizing visual boundaries with available audio transcripts, advanced multi-modal models can aggregate disparate camera angles into cohesive environmental sequences—such as identifying an entire glacial descent or a specific terrain park run.
- Moments and Chapters: Moving from technical ingestion to product-level features, key moments and chapters cater directly to end-user navigation. While key moments isolate high-value standalone excerpts (incorporating shot boundaries and audio cues to ensure editorial integrity), chapters segment extended recordings into structured tables of contents, enabling seamless user discovery.
Implications for Enterprise Media Workflows
The deployment of stable, production-ready APIs for automated video structuring carries significant implications for digital media operations, streaming platforms, and enterprise archiving. By automating the extraction of meaningful metadata, organizations can drastically reduce the manual labor historically required for video indexing, compliance reviews, and content cataloging.
Industry analysts note that the shift toward intelligent, selective video ingestion addresses key pain points in cloud computing expenditures. Processing video data selectively—relying on inexpensive visual signals to map boundaries before invoking heavy vision models—allows enterprises to scale their video AI applications economically. Furthermore, the integration of multimodal embeddings bridges the gap between text-based search queries and visual content retrieval, enabling semantic search capabilities that can pinpoint precise locations within massive media libraries.
As video platforms continue to refine these structural building blocks, the boundary between raw digital media and structured, queryable data continues to blur. Whether applied to automated trailer assembly, accessibility description generation, or complex agentic AI reasoning, the foundational principle remains consistent: optimizing video intelligence requires matching the granularity of the input data precisely to the nature of the inquiry.